The 2026 AI Customer Support Playbook for Modern Teams
Scaling beyond traditional support with an AI-assisted, customer-ready approach to faster resolutions, stronger self-service, and scalable service delivery.
Trusted by companies of all sizes

Why Traditional Customer Support Falls Short
Customer support teams struggle to keep pace as demand grows when service relies on disconnected channels, manual routing, and limited AI-driven automation. Particularly for growing teams:
- Inquiry volumes grow faster than team capacity
- Customers expect instant, AI-assisted support
- Manual work makes scaling expensive
What you’ll learn inside:
-
Why Support Teams Need a New Operating Model
Chapter 1
-
What AI Customer Support Really Means
Chapter 2
-
The 5 Pillars of an AI-Powered Support System
Chapter 3
-
What to Automate First
Chapter 4
-
Building a Knowledge Base That Powers Customers and AI
Chapter 5
-
Designing Workflows That Improve SLA Performance
Chapter 6
-
Getting AI-to-Human Handoff Right
Chapter 7
-
The Metrics That Matter
Chapter 8
-
A 30-Day Rollout Plan
Chapter 9
-
Common Mistakes to Avoid
Chapter 10
-
Conclusion and Next Steps
Chapter 11
Ready to transform your customer support?
Get the step-by-step playbook to streamline AI-assisted support, improve service quality, and create better customer experiences at scale.
Who is the playbook for?
Support Leaders
Scale customer support with AI, reduce repetitive work, and empower teams to resolve issues faster without adding operational complexity.
Customer Experience Leaders
Deliver seamless, context-aware support across every channel with stronger self-service, smarter workflows, and more consistent service quality.
Support Operations Leaders
Streamline workflows, improve visibility, and unlock new efficiencies with AI and automation that help reduce cost-to-serve.
Free to read
The AI Customer Support Playbook
How to automate support, improve SLA compliance, and scale service with AI, knowledge bases, and workflows. Read it here, or get the PDF.
Inside this playbook
- 1. Why support teams need a new operating model
- 2. What AI customer support really means
- 3. The five pillars of an AI-powered support system
- 4. What to automate first
- 5. Building a knowledge base that powers both customers and AI
- 6. Designing workflows that improve SLA compliance
- 7. Getting AI-to-human handoff right
- 8. The metrics that matter
- 9. A 30-day rollout plan
- 10. Common mistakes to avoid
- Conclusion and next steps
- Playbook assets and templates
Introduction
Who this playbook is for
This playbook is for support leaders, support operations teams, service desk managers, and CX leaders who manage multichannel support and want to use AI, automation, knowledge bases, and workflows to improve SLA compliance without sacrificing quality.
The guidance and examples in this guide apply primarily to:
- External customer support teams supporting products or SaaS customers.
- Internal IT or service desk teams handling requests, approvals, and user access updates.
The operating model proposed in this guide is designed for growing teams and enterprise environments, including teams adopting AI for the first time and teams looking to scale support without linear headcount growth.
Chapter 1
Why support teams need a new operating model
The challenge
Support leaders are being asked to deliver faster, more consistent service even as the work itself becomes more complex. Email is still important, but it now sits beside chat, portals, in-app help, phone callbacks, and internal collaboration tools. Product lines change more often. Customers expect context to follow them across channels. Support and service-desk teams are under pressure to respond quickly while also handling more exception paths, more integrations, and more stakeholders.
Traditional support models were built for a simpler environment. They rely heavily on manual triage, queue ownership that lives in a few experienced agents’ heads, and incremental hiring whenever backlogs rise. That can work at low complexity, but it becomes fragile when the same team must adhere to SLAs across multiple channels, products, priorities, and regions.
Why it matters
When support work is not structured, the symptoms are familiar: slow first responses, inconsistent answers, duplicated effort, avoidable escalations, and limited visibility into where time is actually spent. Leaders end up managing symptoms rather than causes. They hire to absorb demand, but the underlying process remains inconsistent, so the same issues return at a larger scale:
- Agents spend too much time reclassifying, reassigning, or gathering missing information before useful work begins.
- Repeated questions crowd out higher-value work that needs judgment, investigation, or coordination.
- Knowledge lives in chat threads, macros, and experienced people instead of a centralized knowledge base.
- Customers repeat their issue when moving from self-service to an agent or from one team to another.
- Support performance depends on heroic effort rather than system design.
What good looks like
Modern support teams need an operating model, not just a ticketing tool. The operating model defines how work enters the system, how it is categorized, who owns it, what can be automated, how knowledge is maintained, when humans intervene, and how performance is improved over time. The help desk or service desk platform matters, but it is only the surface layer. The real leverage comes from consistent intake, reusable knowledge, workflow rules, AI assistance, and a reporting cadence that quickly exposes friction.
Expected outcome: A support organization that can absorb more demand with better consistency, clearer ownership, and less dependence on manual coordination or linear headcount growth.
Chapter 2
What AI customer support really means
The challenge
AI customer support is often treated as a chatbot initiative. That is too narrow and usually not where the best early value comes from. In practice, AI assists across the support lifecycle: it classifies incoming requests, summarizes long conversations, suggests responses, surfaces relevant knowledge, detects missing information, and provides self-service guidance for common issues.
Why it matters
Used well, AI reduces the time agents spend on low-value cognitive work such as reading long threads, searching for the right article, rewriting the same answers, or routing simple tickets manually. Used poorly, it creates confident but unhelpful responses, weak handoffs, and customer frustration. The difference usually comes down to whether AI is grounded in approved knowledge and embedded in clear workflows.
A practical definition
A useful definition of AI customer support is this: a layer of AI assistance that helps customers and agents move through support work faster and with better context. It is not a replacement for support teams. It works best when it draws from trusted knowledge, follows clear workflow rules, and hands work to people when judgment, empathy, exception handling, or risk control is required.
Deployed effectively, it does the following:
- Handles repeated questions through self-service and guided answers.
- Suggests responses for agents to use based on approved content.
- Summarizes tickets to reduce reading time and improve continuity.
- Routes and triages tickets based on intent, language, priority, or account context.
- Surfaces knowledge inside the agent workspace.
- Extracts fields from emails, forms, and chat transcripts.
What effective AI customer support looks like
Good AI support design starts with guardrails. Teams define which tasks AI can handle directly, which require human review, what knowledge sources are approved, and what confidence threshold triggers escalation. Sensitive requests, such as account changes, refunds, changes to a customer’s support plan or access level, contractual exceptions, or security-related issues, should typically be routed to a human or require explicit human approval.
For example, an AI assistant can handle the standard steps for a password reset or invoice copy request, then pass a structured summary to an agent if the case involves identity mismatch, policy exception, or repeated failure. The value is not just faster answers; it is fewer resets, less rework, and better continuity when the issue becomes more complex.
AI governance rules to define before launch
AI support must operate within clear governance rules. These rules define what AI can do, when human oversight is required, and how risk is controlled so AI assistance improves service without creating operational or compliance issues.
Core governance rules
- AI can only use approved knowledge sources.
- Sensitive or high-risk requests must always route to humans.
- AI suggestions and AI actions must be clearly separated.
- Agent corrections must feed continuous improvement.
- AI decisions must be reviewable and auditable.
AI governance decision table
| Use case | AI allowed action | Human review required | Approved knowledge source | Escalation trigger | Risk level | Success metric |
|---|---|---|---|---|---|---|
| Password reset | Guide through standard steps | For exceptions only | Security and identity articles | Identity mismatch or repeated failure | Low | Containment rate |
| Invoice copy | Provide instructions or links | For disputes | Billing policy articles | Contract or pricing exception | Medium | Time saved |
| Subscription question | Suggest next steps | Always | Pricing and policy articles | Plan change request | Medium | Correct routing |
| Refund request | Collect context only | Always | Refund policy | Refund or exception detected | High | Escalation accuracy |
| Access or entitlement request | Classify and route | Always | Access and approval policies | Restricted access or missing approval | High | Correct routing |
| Security-related issue | Summarize and escalate | Always | Security runbooks | Security signal detected | Critical | Zero incorrect resolutions |
Confidence and escalation
AI should escalate issues when confidence falls below the defined threshold; when billing, contractual, security, or entitlement data is involved; or when repeated failure or customer frustration is detected.
Oversight improvement
Knowledge owners approve AI content sources. Support operations teams review routing and automation rules. Agents can correct AI summaries and suggestions, and those corrections should be reviewed regularly to improve quality.
Expected outcome: Higher agent capacity and faster service without treating AI as a substitute for people or process discipline.
Chapter 3
The five pillars of an AI-powered support system
The challenge
Many teams try to bolt AI to fragmented support processes. That rarely works because AI depends on the system around it. If channels are fragmented, knowledge is weak, and ownership is unclear, AI will mostly accelerate confusion. The better approach is to design an integrated operating model based on five connected pillars: omnichannel support intake, knowledge base, workflow automation, AI assistance, and reporting.
Why it matters
These pillars give support leaders a practical frame for evaluating service maturity. They also help teams avoid one-dimensional decisions, such as adding a chatbot without fixing routing, or improving knowledge without connecting it to agent workflows. In strong systems, the pillars reinforce each other.
- Omnichannel support intakeBring email, chat, portal, phone, and messaging into a common intake model. One case record, standardized categories, and required context.
- Knowledge baseProvide trusted answers for customers, agents, and AI based on searchable, owned, and reviewed content with a clear structure.
- Workflow automationAutomatically move work based on rules and SLAs, routing, priority, approvals, and escalations that reduce manual triage.
- AI assistanceHelp with self-service, triage, and agent productivity. Generate problem summaries, draft replies, and detect intent all under human oversight.
- ReportingIdentify where performance improves or breaks with a shared view of speed, quality, backlog, deflection, and automation outcomes.
How the pillars work together
Omnichannel intake supplies the structured data needed for routing and measurement. The knowledge base improves both self-service and agent accuracy. Workflow automation prevents SLA breaches by enforcing ownership and timing. AI uses knowledge and workflow context to make assistance relevant. Reporting closes the loop by exposing article gaps, broken rules, and high-friction case types.
Consider a billing support case: A customer starts a chat with a routine invoice question. The AI assistant surfaces the relevant article and provides the standard answer, but the customer then reveals it is a contract exception. The automation workflow captures account details, routes the case to the right specialist queue, applies the correct SLA, and provides a summary of the conversation and the article already shown. Reporting later shows whether the article was effective, whether routing was correct, and how long it took to resolve the exception.
What good looks like
- An AI-powered support system works when intake, knowledge, workflow automation, AI assistance, and reporting operate as one connected model.
- One knowledge model used by customers, agents, and AI.
- One set of routing and escalation rules aligned to SLA commitments.
- One review cadence that connects metrics to content and process improvement.
Expected outcome: A support system where speed, consistency, self-service, and visibility improve together instead of through disconnected point fixes.
Chapter 4
What to automate first
The challenge
A common rollout mistake is trying to automate too much, too early. Teams build a broad program before they have proven the AI-enhanced system’s value in a few practical use cases. Others automate a broken process and simply make the broken process run faster. The best starting point is repeatable work with clear inputs, known outputs, and visible impact.
Why it matters
Early wins build trust with agents, leaders, and adjacent teams. They also reveal where knowledge is incomplete, where workflows need adjustment, and where AI needs a human backstop. Support teams do not need a big-bang transformation to make progress. They need a sensible order of operations.
- Quick winsAuto-acknowledgements, tagging, knowledge suggestions
- Agent productivitySummaries, draft replies, field extraction, next steps
- Scale-oriented automationIntent routing, approvals, proactive escalations
Recommended actions
- Review top contact reasons and rank them by volume, repeatability, risk, and SLA impact.
- Select three starter use cases with clear fallback paths.
- Measure time saved, routing accuracy, and quality impact before expanding.
Expected outcome: Faster time to value, less rollout resistance, and a stronger foundation for larger automation programs.
Chapter 5
Building a knowledge base that powers both customers and AI
The challenge
Knowledge bases often fail for the same reason support processes fail: they are treated as static content libraries instead of operating assets. Articles become outdated, are written in internal language, or become disconnected from how customers actually ask questions. When that happens, self-service underperforms, AI answers become unreliable, and agents fall back to personal notes or undocumented institutional knowledge.
Why it matters
Knowledge quality is a direct constraint on AI quality. If the source content is incomplete, ambiguous, or outdated, AI will repeat those weaknesses at scale. The same is true for agent efficiency. A strong knowledge base shortens search time, improves answer consistency, and reduces onboarding time for new agents.
What good looks like
High-performing knowledge bases are built around customer intent, clear resolution steps, known exceptions, escalation cues, ownership, and review discipline. Each article should be easy for customers, agents, and AI systems to reuse consistently. Effective knowledge bases have these characteristics:
- One issue or task per article, with a clear user goal.
- A consistent structure: summary, steps, exceptions, and escalation cues.
- Taxonomy and naming that reflect how customers search and how teams route work.
- Ownership, review dates, and version discipline.
- Keywords and synonyms that match the language customers actually use.
Recommended actions
- Focus first on high-volume, high-impact issues that drive agent workload or SLA misses.
- Standardize knowledge with a consistent article template, clear ownership, and a simple review process.
- Use ticket data to identify gaps or outdated content, and track both customer and agent usage.
- Document standard policies (e.g., invoice corrections, required info, exceptions) to enable self-service, agent consistency, and reliable AI support.
Example
In BoldDesk, help articles can be structured, owned, and linked directly to ticket types and agent workflows. This allows the same content to power self-service, agent assistance, and AI suggestions. Usage data and ticket trends can be used to identify article gaps, outdated content, and improvement opportunities.
Expected outcome: A knowledge base that improves self-service, strengthens AI responses, and makes agent performance less dependent on memory or individual experience.
Chapter 6
Designing workflows that improve SLA compliance
The challenge
SLA breaches often occur due to incorrect routing and unclear ownership rather than poor agent effort. Tickets arrive without the right category or priority, sit in the wrong queue, wait for missing information, or bounce between teams before real work begins. By the time a manager notices the issue, the clock has already been running against the team.
Why it matters
SLA compliance is shaped in the first minutes of a case’s lifecycle. If intake is inconsistent, ownership is ambiguous, or escalation rules take effect too late, the team is forced into reactive recovery. Support leaders should treat workflow design as one of the most important factors influencing response time, resolution time, and customer confidence.
What good looks like
High-performing support workflows reduce intake ambiguity through standardized fields, smart prioritization, skill-based routing, clear ownership, and proactive escalations. They include the following:
- Intake rules that capture the product, issue type, region, account tier, or requester department needed for routing.
- A defined priority model rather than free-form labels.
- Queue or skill-based assignment rules that remove manual triage for common case types.
- Escalation triggers for response and resolution milestones, not just breaches.
- Status logic that distinguishes waiting on the customer from waiting on an internal dependency.
- One accountable owner, even when specialists collaborate behind the scenes.
Recommended actions
- Map the end-to-end case journey and identify delay points like waiting, reclassification, handoffs, and missing information.
- Redesign workflows starting with standardized routing and prioritization for the highest-volume case types.
- Layer in escalation rules, approvals, and automated status updates gradually. Simplify paths before over-automating.
- Structure common flows (e.g., access or support plan change requests) so ownership, approvals, and timing are clear, and SLAs are easier to maintain.
Example
BoldDesk allows teams to apply automation rules for priority, assignment, and escalation based on ticket attributes and SLA terms. Timers, status changes, and ownership rules help ensure SLAs are maintained by system design rather than reactive intervention.
Expected outcome: Better SLA compliance, fewer avoidable escalations, and greater visibility into where cases slow down.
Chapter 7
Getting AI-to-human handoff right
The challenge
The worst AI support experience is not a failed answer; it is a failed handoff. When customers have to repeat themselves after interacting with an assistant, confidence drops quickly. The same happens when agents inherit a case without knowing what has already been asked, what the customer has tried, or why the issue should be escalated.
Why it matters
Support quality depends on continuity and context. If handoff is weak, any gains from self-service or automation are offset by longer handling time, customer frustration, and repeat contacts. Good handoff design is one of the clearest signs that a support team treats AI as part of an operating model rather than an isolated tool.
What good looks like
When AI can’t resolve the issue confidently, it should pass a structured payload to the human agent: customer intent, a summary of the conversation, relevant account or requester details, steps already attempted, knowledge base articles shown, and any signals about urgency or sentiment. The customer should understand that the case is continuing, not starting over.
Handoff payload
- Customer intent
- Conversation summary
- Steps already tried
- Knowledge base articles
No repetition · Full context · Continuity
Recommended actions
- Define transfer triggers by risk, confidence, and policy rather than waiting for obvious failure.
- Keep the conversation in the same ticket or thread where possible so context travels with the case.
- Show the transcript and AI summary to the agent side by side.
- Let agents correct AI summaries and use those corrections to improve the system over time.
- Measure repeated questions after transfer and time to first meaningful agent response.
Example
In BoldDesk, AI-generated summaries, conversation histories, and suggested knowledge base articles appear directly in the agent workspace. This keeps context intact during escalation and reduces repeated questions, while giving agents control to review and correct AI output.
Expected outcome: A lower-friction support journey with shorter handling time, fewer repeated questions, and higher customer confidence in the provided service.
Chapter 8
The metrics that matter
The challenge
Support teams often overfocus on volume metrics and undermeasure experience, quality, and the impact of automation. Others optimize first response time in a way that hides the real customer outcome. Metrics only help when they reflect how the service actually performs from intake to resolution.
Why it matters
Metrics shape behavior. Optimizing for speed alone can erode quality, while focusing only on satisfaction can conceal bottlenecks. A balanced scorecard, spanning speed, quality, workload, and automation, shows whether AI-powered support is truly improving outcomes or just shifting effort. The following metrics form the foundation of that scorecard.
| Metric | What it measures | Why it matters | Formula |
|---|---|---|---|
| First response time | The elapsed time between ticket creation and the first meaningful response, whether human or automated. | First response time sets customer expectations and strongly influences perceived responsiveness, even when total resolution time is longer. | First meaningful response time − Ticket creation time |
| Resolution time | The total time taken to fully resolve a ticket, from creation to solved or closed status. | This metric reflects end-to-end execution efficiency and highlights process friction, handoffs, or escalation delays. | Solved or closed time − Ticket creation time |
| SLA compliance | The percentage of tickets that meet defined response or resolution service-level agreements. | SLAs translate customer expectations into measurable commitments and reveal systemic risk when they are consistently missed. | (Tickets meeting SLA ÷ Total SLA-applicable tickets) × 100 |
| Deflection rate | The percentage of issues resolved through self-service or automation before a support ticket is created. | High deflection, paired with strong satisfaction signals, reduces agent workload while maintaining customer autonomy. | (Self-service resolutions without ticket creation ÷ Total self-service issue resolution attempts) × 100 |
| Backlog | All unresolved tickets at a given point in time, and how that queue grows, shrinks, or stagnates. | Backlog indicates the balance between system capacity and demand. Rising backlog often precedes SLA breaches and burnout. | Key indicators: open tickets by age; backlog growth or reduction rate; distribution by priority or category. |
| CSAT (customer satisfaction) | Customer satisfaction following a meaningful interaction or issue resolution. | Speed without satisfaction fails customers. Satisfaction without speed doesn’t scale. CSAT anchors operational metrics to customer perception. | Post-resolution survey rating (e.g., 1–5 rating scale or satisfied/unsatisfied). |
Recommended actions
- Set a clear baseline before rollout and measure improvement against it.
- Review metrics by channel, priority, issue type, and customer segment rather than only in aggregate.
- Pair operational metrics with quality reviews, article feedback, and agent observations.
- Focus on outcomes, such as faster resolution, better consistency, and easier scalability, rather than proving AI usage.
Example
BoldDesk’s built-in dashboards and SLA reports help teams understand where automation improves outcomes and where manual effort remains high. Metrics such as routing accuracy, escalation frequency, and backlog age connect operational data to continuous improvement.
Expected outcome: A balanced measurement system that shows whether AI, automation, workflows, and knowledge are improving service speed, quality, workload, and customer outcomes.
Chapter 9
A 30-day rollout plan
The challenge
Support leaders rarely have the luxury of a long transformation runway. They need a practical starting plan that creates momentum, surfaces gaps quickly, and proves whether the model will work in day-to-day operations.
Why it matters
A 30-day pilot program is long enough to create real learning but short enough to keep scope under control. It also forces the team to prioritize a small number of meaningful workflows instead of trying to redesign everything at once.
- Week 1: Audit and prioritizeFocus: Review top contact reasons, volumes, channels, SLA breaches, reassignments, and repeat contacts. Select three starting use cases.Deliverables: Current-state map, use-case shortlist, and success metrics.
- Week 2: Strengthen knowledgeFocus: Build or refresh top articles, define templates, assign owners, close content gaps, and connect articles to case types.Deliverables: Working set of articles, review cadence, and knowledge standards.
- Week 3: Launch automation and AI assistanceFocus: Implement routing rules, acknowledgment and escalation automations, AI summaries, article suggestions, and one self-service pilot with fallback paths.Deliverables: Live pilot system with guardrails, trained agents, and clear escalation logic.
- Week 4: Measure and optimizeFocus: Review routing accuracy, response and resolution impact, handoff quality, article usage, and feedback from agents and customers.Deliverables: Pilot results, improvement backlog, and rollout decision.
Sample 30-day pilot
The objective of a 30-day rollout is not broad automation; it is to validate that the operating model—intake, knowledge, workflow, AI assistance, and reporting—functions effectively under real conditions. A successful pilot is deliberately limited in scope, clearly governed, and measured against predefined success criteria.
1. Pilot scope definition
Selected use cases. Choose a small set of repeatable, low-risk requests that represent meaningful volume and operational friction, such as:
- Password resets.
- Invoice copy requests.
- Subscription or plan clarifications.
Included channels.
- Customer portal
Chat, phone, and high-touch channels should be excluded from the initial pilot to minimize complexity and variability.
Why this works. These requests occur frequently, follow predictable steps, and depend heavily on knowledge. That makes them ideal for testing intake, routing, articles, and AI assistance without risking customer trust.
2. Knowledge: How much is enough?
You do not need a full knowledge base to start. Minimum requirements:
- One clear article per use case (three total).
- Each article includes: what the customer is trying to do; step-by-step resolution; common exceptions; when to hand off to an agent.
- One person owns each article.
Focus on clarity and accuracy, not volume.
3. Who should be involved
Keep the pilot team small.
- One support operations or team lead.
- One frontline agent per use case.
- One person is responsible for knowledge.
- One admin or system owner.
Review cadence.
- Daily check-ins during the first week (15–20 minutes).
- Weekly reviews after launch.
Early reviews should focus on misrouted tickets, missing information, and unclear articles.
4. Define success before you start
Agree on success metrics in advance so expansion decisions are objective. The pilot is working if results are close to the following:
- 20% fewer tickets needing manual triage.
- At least 80% correct routing.
- 10% faster first response time.
- No meaningful drop in CSAT.
- Agents actively use articles or AI summaries.
These numbers are guides, not hard rules. Consistency matters more than perfection.
5. When to expand
Expand only when:
- Routing is stable and predictable.
- Agents trust the workflows and suggestions.
- Articles are being used and referenced.
- Escalation errors are rare and understood.
If these conditions are not met, extend the pilot period and fix issues before adding more use cases or channels.
Outcome
A focused 30-day pilot gives the team real learning, builds agent confidence, and creates a clear decision point. Teams either move forward with evidence or pause with clarity—both outcomes prevent costly missteps.
Pro tip
Hold a weekly review involving support leadership, support operations, and owners responsible for knowledge. This review is where small issues are corrected before they become rollout blockers.
Expected outcome: A focused pilot that gives the team a practical proof point, a clear improvement backlog, and a decision basis for broader rollout.
Chapter 10
Common mistakes to avoid
The challenge
Most support AI programs do not fail because the ideas are wrong. They fail because the order of operations is wrong, governance is weak, or teams mistake tool usage for service improvement. Avoiding a few predictable mistakes can save months of rework.
What support teams often get wrong
- Starting with AI before fixing intake and knowledge. Weak data and weak content create weak outcomes.
- Automating exceptions before standard cases. Start where the path is repeatable and measurable.
- Treating auto-acknowledgments as real response improvement. Customers care about meaningful progress, not just confirmation.
- Forcing customers into bot-only journeys with no clear path to a person when risk or complexity rises.
- Letting knowledge become everyone’s job and therefore no one’s job. Content needs clear ownership and review dates.
- Measuring activity instead of outcomes. Adoption alone does not prove that service improved.
- Ignoring agent feedback. If agents do not trust the knowledge or the suggestions, the model will not scale.
- Rolling out too broadly before the pilot is stable. It is better to tune a few high-value flows than to spread thinly across many.
The common thread is simple: mature support teams treat AI, workflows, and knowledge as operating disciplines. They do not deploy them as disconnected features.
Conclusion
Conclusion and next steps
Support teams do not scale well by adding channels, bots, or automations in isolation. They scale when the operating model is designed to make work visible, standardize the repeatable parts, preserve context, and give agents the knowledge and workflow support they need to resolve exceptions well. AI has an important role in that model, but its value depends on the structure around it.
The most effective next step is usually an honest audit: review how work enters your system, where SLA compliance risk accumulates, how knowledge is maintained, and where agents spend time on repetitive effort. From there, prioritize a small number of high-value improvements, strengthen the knowledge base, and test automation and AI assistance in controlled workflows.
The common thread
Mature support teams treat AI, workflows, and knowledge as operating disciplines. They do not deploy them as disconnected features.
Action item
Assess your support workflow gaps, knowledge-base readiness, and SLA risk points, and then evaluate whether your current support platform can operationalize these practices. If it cannot, use a focused demo or trial against your real support scenarios before expanding further.
Appendix
Playbook assets and templates
Appendix A: AI support readiness checklist
Purpose. Evaluate your support system before enabling AI in production to avoid low-trust or fragile deployments.
| Area | Checklist |
|---|---|
| Intake |
|
| Knowledge |
|
| Workflow |
|
| AI and governance |
|
Appendix B: Top contact reason scoring matrix
Purpose. Help teams objectively decide what to automate first.
| Criterion | 1 – Low | 2 – Medium | 3 – High |
|---|---|---|---|
| Volume | Rare | Moderate | Frequent |
| Predictability | Many exceptions | Some variation | Very consistent |
| Risk | High (security, money) | Medium | Low |
| SLA sensitivity | Minimal | Moderate | High |
| Knowledge availability | Weak or missing | Partial | Strong |
Scoring guidance.
- Start with use cases scoring 12 or higher.
- Avoid high-risk, low-knowledge combinations.
- Re-score after 30 days to track improvement.
Appendix C: Knowledge base article template
Purpose. Ensure articles work equally well for customers, agents, and AI.
- Title: clear, customer-language phrasing.
- Purpose: what problem does this article help resolve?
- When to use: supported request types or triggers.
- Resolution steps: step one, step two, step three (each a clear action).
- Exceptions: what does not fit this flow? Edge cases to watch for.
- Escalate when: conditions requiring human intervention; policy or risk thresholds.
- Last reviewed by or article owner.
Appendix D: Workflow automation rule examples
Purpose. Provide starter logic that teams can adapt instead of designing from scratch.
Routing
- If issue_type = password_reset → assign to tier 1 queue
- If product = billing and account_tier = enterprise → assign to senior queue
Prioritization
- If customer tier = premium → priority = high
- If request is flagged “service down” → priority = urgent
Status management
- If waiting on customer → pause SLA
- If internal dependency → mark as blocked
Automation principle: Automate decisions, not exceptions.
Appendix E: SLA escalation rule examples
Purpose. Prevent SLA failures by acting before a breach occurs.
Response SLA
- 50% elapsed → notify owner
- 75% elapsed → escalate to team lead
Resolution SLA
- At risk → notify manager
- Breach likely → priority override
Best practices
- Separate response and resolution logic
- Never escalate only after a breach
Appendix F: AI-to-human handoff payload template
Purpose. Ensure continuity when AI escalates to an agent.
Required handoff fields
- Customer intent (normalized)
- Short interaction summary
- Actions already taken
- Knowledge base articles shown
- Escalation reason (confidence, policy, exception)
- Urgency or sentiment signals (if available)
Success measure: Agents should not need to ask repeat questions.
Appendix G: 30-day rollout checklist
Purpose. Evaluate your support system as you roll out the AI support pilot to avoid low-trust or fragile deployments.
| Week | Checklist |
|---|---|
| Week 1 |
|
| Week 2 |
|
| Week 3 |
|
| Week 4 |
|
Appendix H: Pilot success criteria and expansion checklist
Purpose. Clarifies the decision about the pilot plan. A pilot is ready to expand when:
- Routing accuracy ≥ 80%
- Manual triage reduced (~20%)
- First response time improved
- CSAT did not decline
- Agents trust suggestions
- Escalation errors are rare
If two or more are not met, extend the pilot and refine.
A Modern AI Customer Support Model Built for 2026
AI, automation, and experience-led support help teams scale smarter without adding complexity.
AI That Strengthens Agent Performance
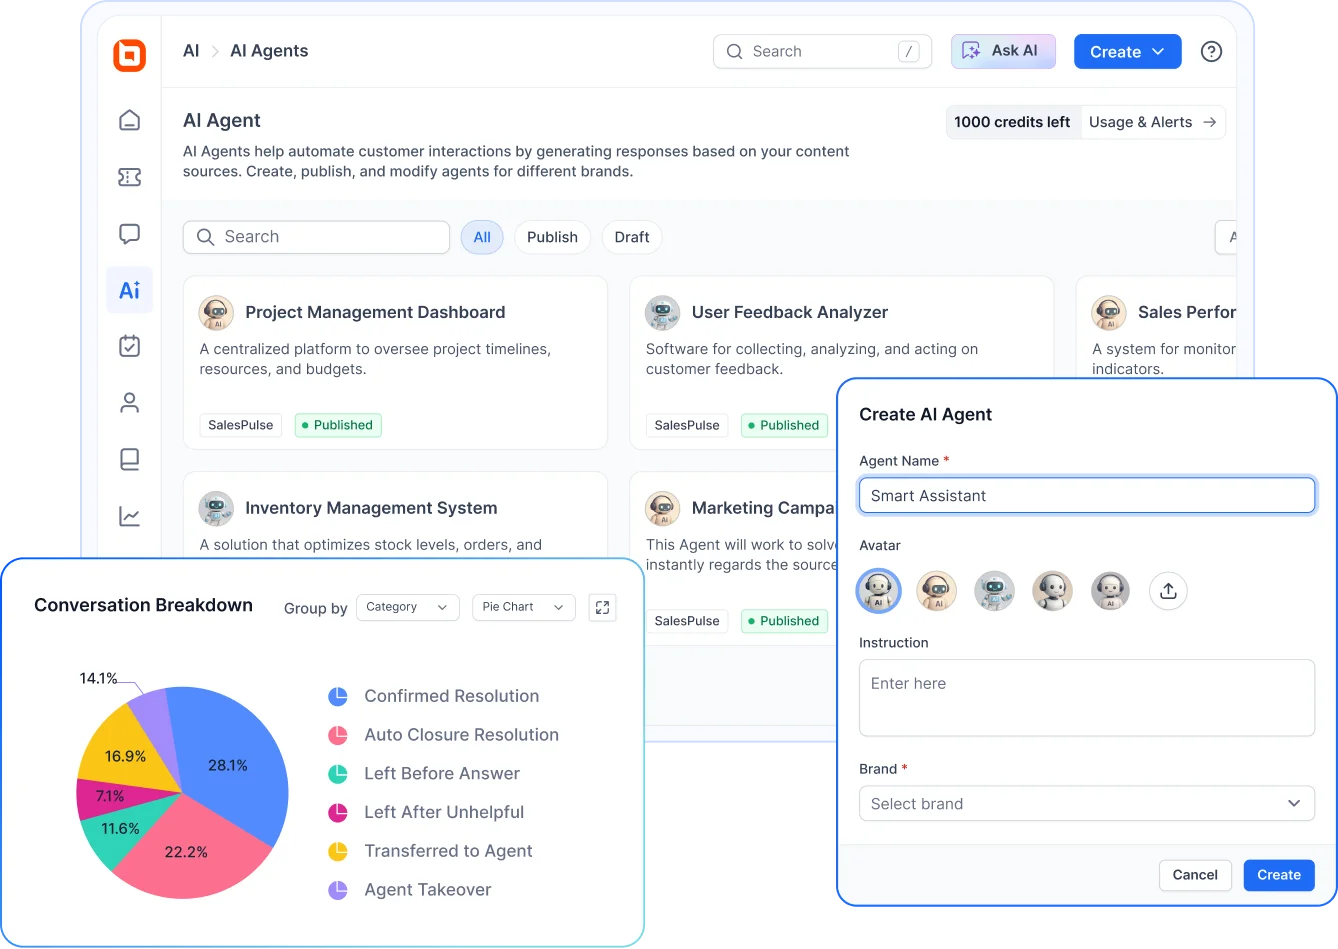
Automate routine inquiries, accelerate complex conversations with AI assistance, and reduce cost-to-serve.
One Place For Every Customer Request
Give customers a unified support experience across chat, email, self-service, and forms in one platform.
Insights That Drive Better Experiences
Track CSAT, response time, and reopen through dashboards to uncover what truly impacts customer experience.
The Impact of an AI-First Support-Ready Approach
Real-world data from BoldDesk customers demonstrates how AI-assisted customer support enhances performance and reduces costs today.
3X
Faster replies with BoldDesk AI Copilot.
Up to70%
Of recurring conversations auto resolved with BoldDesk AI.
20%
Average CSAT increase with BoldDesk AI.
Build Your AI-First Support Model with BoldDesk in 2026
Get the full AI customer support playbook for scaling support, improving service quality, and lowering cost-to-serve with BoldDesk.